Why Complex Tables Are the Hardest Part of an Accessible PDF
The table that looks fine and reads as noise
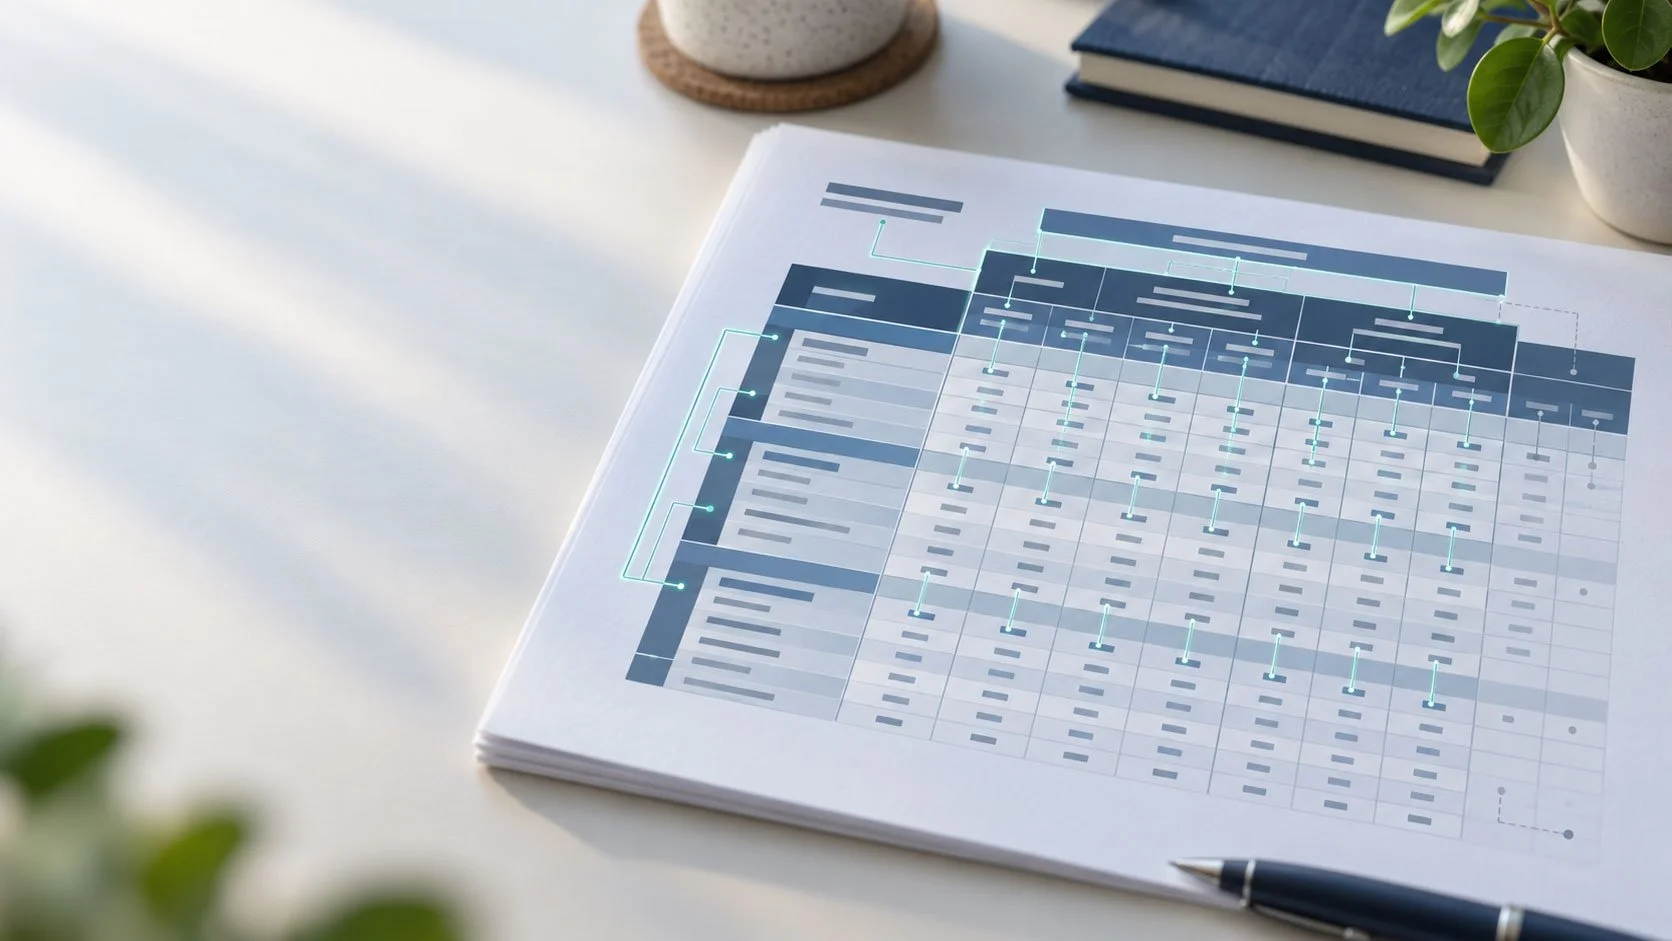
Open any adopted budget from a city, a school district, or a state agency and turn to the expenditure summary. A sighted reader sees the structure at a glance: a program name spanning several columns, fiscal years underneath it, a subtotal row, then the next program. The meaning lives in how those cells relate to one another.
A screen reader user gets none of that from the layout. What they hear depends entirely on the structure tagged inside the PDF. If that structure is wrong, a figure is announced with no program, no year, and no hint of whether it is a line item or a total. Every number is present. The meaning is not.
For IT directors working through an ADA Title II document inventory, tables deserve their own line in the plan. They hold some of the most important public information an organization publishes, and they are where remediation most often fails without anyone noticing.
What accessible means for a data table
WCAG 2.1 success criterion 1.3.1 asks that information and relationships shown visually also be available programmatically. For a table, that means every data cell has to be tied to the headers that give it meaning.
PDF/UA offers two ways to make that connection:
- Scope attributes, which mark a header as applying to its column or its row. This works well for simple grids.
- Headers and IDs, where each header receives a unique identifier and each data cell lists the specific headers it belongs to. This explicit method is what complex tables need.
Choosing the right method for each table is the first decision that separates real remediation from simply adding tags.
Four table patterns that trip up conventional remediation
Simple tables are rarely the issue. The four patterns below appear constantly in public sector documents, and each one can look correct on screen while failing a screen reader user.
Headers that span several columns
A header such as "Capital Projects" stretched across three fiscal-year columns is obvious visually. When remediation applies scope to the individual cells beneath it, the link between that spanning header and the data below it disappears.
Headers stacked in layers
Multi-year budgets often place a category above a row of years. Each data cell needs to reference both levels. Remediation that connects cells only to the nearest header row drops the category, so the listener hears a year with no idea which program it describes.
Row headers that cover a group of rows
Fee schedules, grant summaries, and staffing tables often use one row header for several rows. When scope is applied only to the first row in the group, the remaining rows have no row header at all.
Irregular layouts
Real documents include spacer cells, totals mixed in with data, uneven column widths, and groupings shown only with shading. Automated tools can mistake a spacer for data or a total row for a header, and the resulting structure misleads the reader instead of guiding them.
Why this matters beyond the checker
Tables are concentrated in exactly the documents residents, journalists, and board members rely on: budgets, audits, bid tabulations, election results, and board packets. When the relationships in those tables are missing, a screen reader user is shut out of the information entirely, not partially.
A passing score on an automated checker does not settle the question. A table can carry tags, look correct, and clear basic checks while still failing to tell a listener how its numbers connect. Accessibility and the checker score are related, but they are not the same thing.
How AoD handles complex tables
Accessibility on Demand treats a table as a structure to understand before it treats it as a set of tags to apply. AoD maps the full header layout first, including spanning cells, layered headers, row groups, and total rows. It then decides whether scope attributes are enough or whether the table needs explicit headers and IDs, and it builds the associations each data cell requires.
This is work AI is well suited to. Table tagging follows published rules, and applying those rules consistently across thousands of documents is where automation outperforms manual effort. AoD converts PDFs into accessible documents in minutes, and AoD reports that its platform reduces processing time by 10X.
For documents that allow no margin for error, AoD also offers a level with expert human review, where specialists check the proposed structure against the visual table before the file is finalized.
The cost difference is significant for any organization with a real backlog. Manual remediation typically runs $8 to $25 per page for standard documents and $50 to $100 per page for fillable forms. AoD at Level 2 costs $1.80 per page, and Level 2 handles tables, images, and fillable forms.
What your organization receives is a remediated source file it owns outright. There is no overlay to maintain and no subscription required to keep the document accessible. It stays accessible when it is downloaded, printed, emailed, or moved to a new website.
How to check a table yourself
The most reliable test uses the same tools your residents do. With a screen reader such as NVDA or JAWS:
- Move through the table one cell at a time.
- Confirm each value is announced with its row header and column header.
- In layered tables, confirm both the category and the subheader are announced.
- Where one row header covers several rows, confirm it is announced on every row in the group.
AoD's guidance puts this at roughly two minutes per table. It is a small investment, and it catches problems that automated checkers miss.
A practical place to start
Most organizations do not know how many of their PDFs contain complex tables until they look. A short sample is usually enough to show where the difficult documents sit and what clearing them would cost.
RDS offers a free assessment of two to four of your documents, with a clear picture of what remediation involves for your inventory.